 CSV
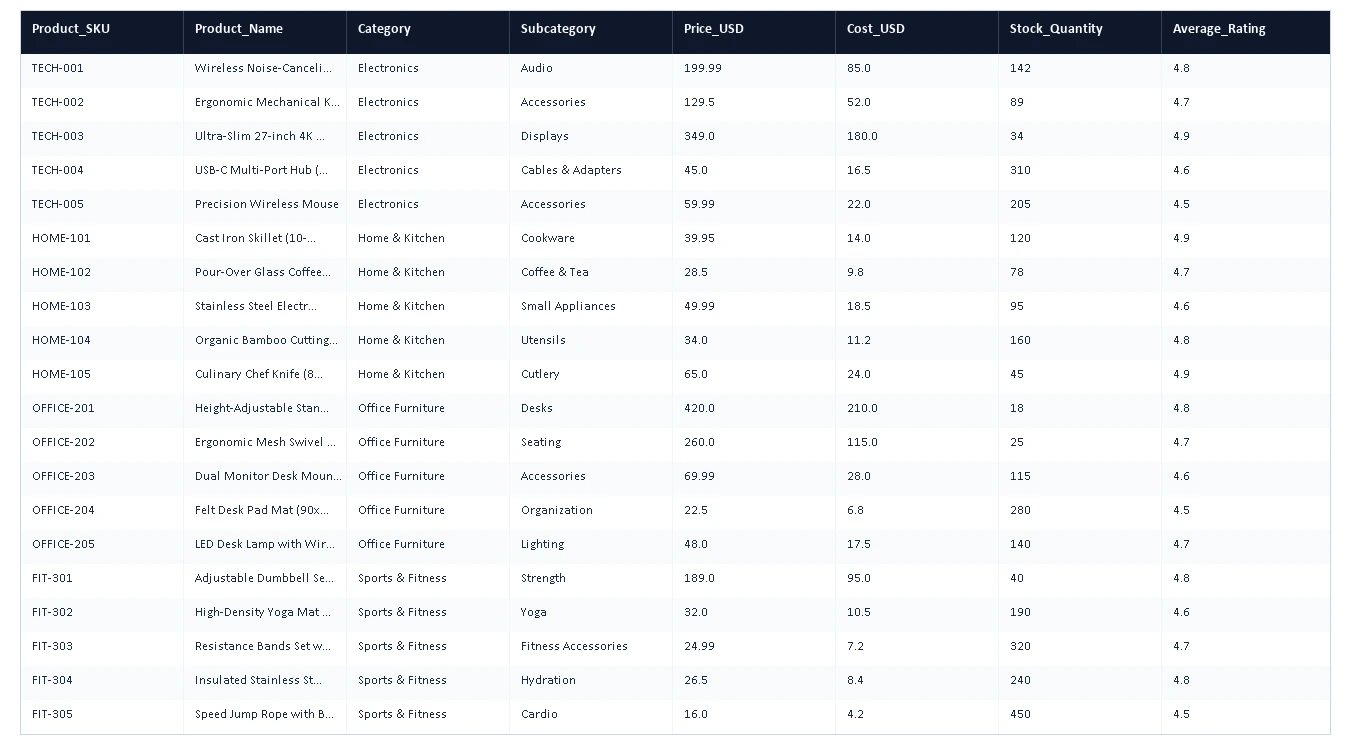
Sample E-Commerce Products Catalog Dataset CSV
Download a 50-item e-commerce product catalog dataset in CSV format. Includes SKUs, categories, retail …
 CSV
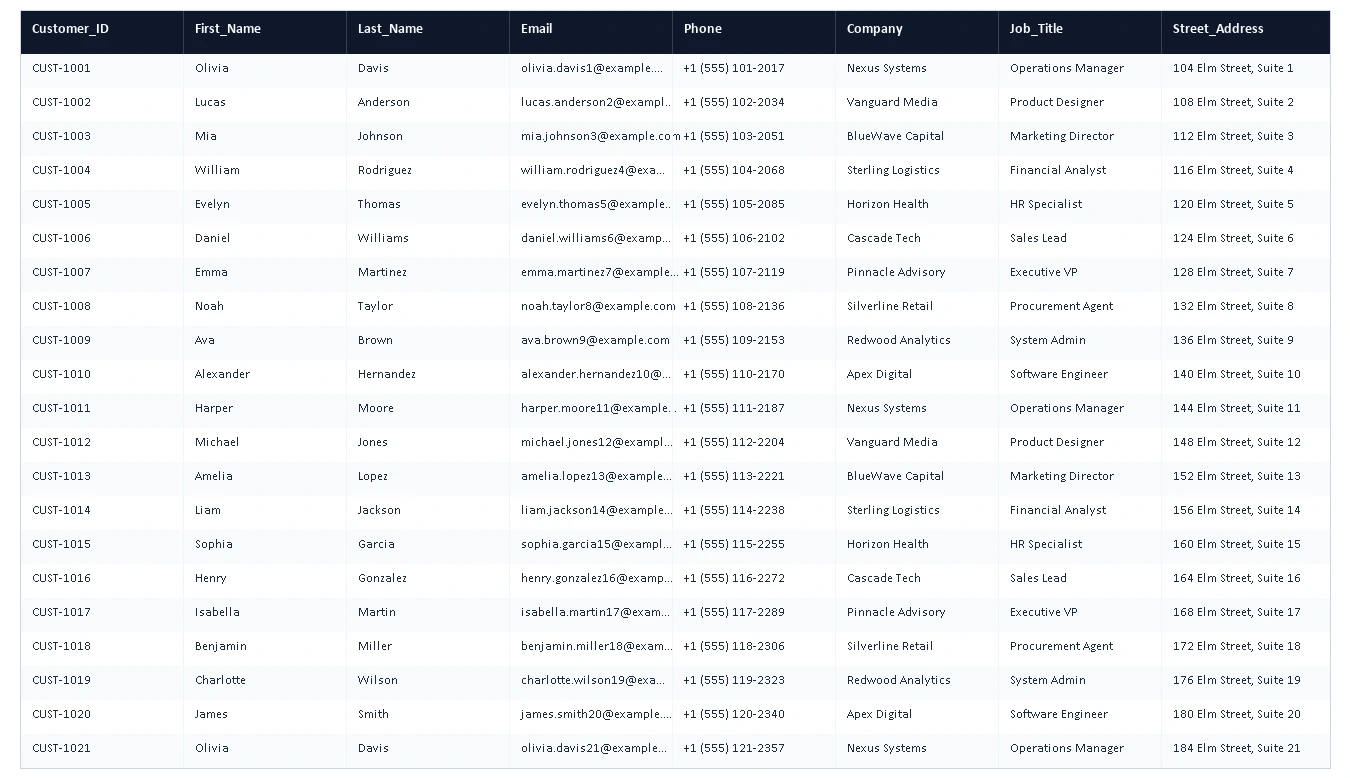
Sample US Customers Mock Dataset CSV (100 Rows)
Download a clean mock dataset of 100 US customers in CSV format. Realistic names, emails, addresses, and dates …
 CSV
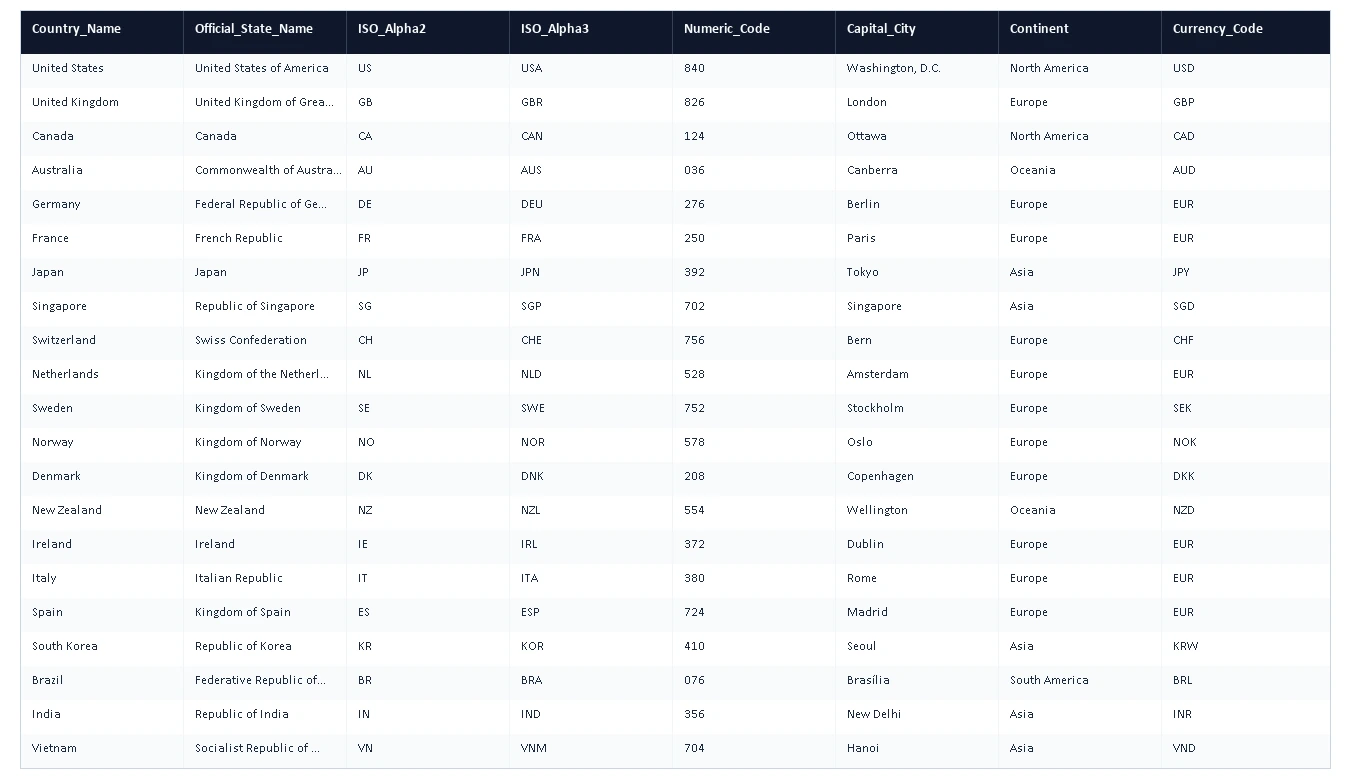
World Countries & Capitals ISO Dataset CSV
Download a reference dataset of world countries and capitals in CSV. Includes ISO-3166 codes, continents, and …
Clean, Structured CSV Tabular Datasets for Developers & Analysts
Software engineers, database administrators, and data analysts frequently require realistic, pre-structured tabular datasets to seed local test databases, benchmark query performance, test e-commerce carts, and train machine learning models.
SnugDocs provides cleanly formatted, RFC 4180-compliant CSV datasets ready for immediate integration.
Data Engineering Standards
- Standard RFC 4180 Format: Strictly formatted with comma delimiters, standard line breaks (
\n), and double-quote escaping for text containing special characters or punctuation. - Privacy Compliant Mock Data: All customer and billing records are generated synthetically using realistic distribution algorithms, ensuring total compliance with GDPR, HIPAA, and CCPA guidelines.
- Database & BI Tool Ready: Header columns utilize clean, normalized identifier naming conventions (
first_name,email_address,unit_price_usd) compatible with SQL engines and BI platforms (Tableau, Power BI, Metabase).
Frequently Asked Questions
What character encoding and delimiter standard do these CSV files use?
All datasets are encoded in standard UTF-8 without Byte Order Mark (BOM) and use standard comma delimiters (RFC 4180), ensuring seamless imports into any programming language or database.
Is the customer and commercial data real or synthetically generated?
All personal identifiers (names, emails, phone numbers, addresses) are 100% synthetically generated for privacy compliance (GDPR/CCPA safe). Country codes and capitals conform strictly to ISO-3166 standards.
Can I import these CSV files directly into PostgreSQL, MySQL, and pandas?
Yes. Every CSV includes a clean header row with standardized snake_case column names, valid data types, and escaped quotation marks for immediate loading via COPY, LOAD DATA INFILE, or pd.read_csv().